Correlating LLM Inference Spans With Agent Outcome Metrics
Linking inference steps to quality outcomes turns production failures into systematic improvements.
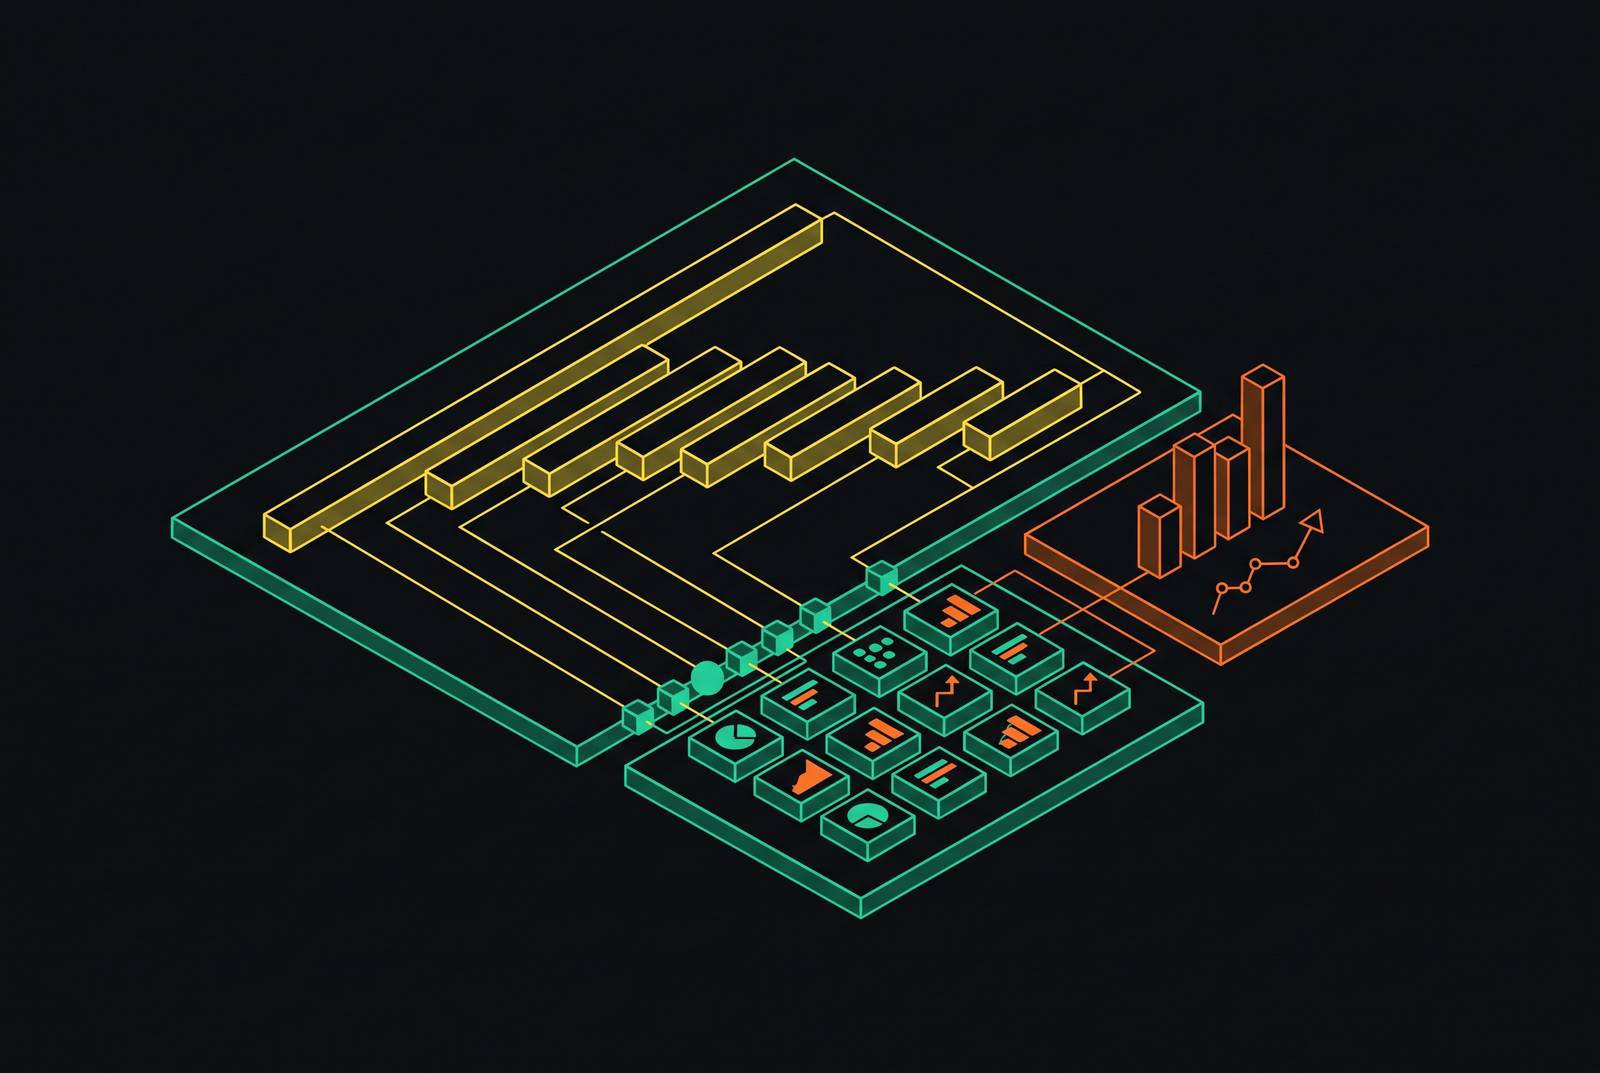
LLM inference spans can help explain why an agent succeeds, wastes money, or passes an error downstream. But collecting them is not enough. To correlate those spans with agent outcome metrics, teams must link the steps that ran to judgments of their quality and the goals they completed. The payoff is a feedback loop that turns production failures into tested improvements, rather than traces that merely explain what went wrong.
Why standard distributed tracing breaks for multi-step agent execution
Standard APM assumes a request-response service where the same input reliably gives the same output and failures are reported as exceptions or status codes. An agent breaks both assumptions in one request. It may make several model calls, retrieve documents, read memory, choose tools, and hand work to another agent. Each step can run successfully but still produce something that makes the next step wrong. An HTTP 200 cannot distinguish those failures from useful work.
A wrong retrieval can change the plan, a hallucinated argument can corrupt a tool call, and a handoff can lose context. By the time the failure becomes visible, downstream steps may already have acted on bad state. Latency, request rate, and error rate also miss hallucinations, prompt drift, and token-based cost accumulation. Requests per second cannot show how much workflows cost or how well they perform when their calls use different numbers of tokens.
The four domains agent observability must cover that LLM tracing alone does not
Agent observability therefore needs a map of what to track about actions as well as more detail about generated text. The first domain is reasoning traces, including the intermediate decisions and planning outputs an agent produces before acting. These help establish whether it understood the task. The second domain is tool call behavior, which records the tools chosen, their arguments, execution order, and returned results. A plausible plan means little if the action it triggers is wrong.
The third domain is state changes and side effects, which include database writes, external API requests, and changes to files. What persisted after the agent finished its run? A tool’s returned result gives only part of that answer. The fourth domain is error handling and recovery, which covers retries, silent failures, and fallback paths. A success/failure log can make graceful recovery and repeated attempts that never make progress look alike.
Traditional LLM observability concentrates on reasoning and output generation, while the other domains require instrumentation around execution. That distinction also separates observation from enforcement. Recording what an agent planned to do or a state change it completed helps explain its behavior, but stopping an unsafe action takes a control that acts before execution. The trace must capture enough to show both what the agent chose and what actually changed.
The span taxonomy that gives agent execution a structured vocabulary
A typed span hierarchy gives those requirements a queryable structure. LLM spans describe individual model calls, capturing prompts, completions, token counts, cost, and model parameters. Tool/function-call spans record arguments, raw results, latency, and success or failure. Retriever spans capture the query, returned documents, and retrieval latency, while agent-orchestration spans describe planning, routing, and sub-agent handoffs.
The recommended hierarchy starts with a top-level span for the agent session or user turn. Reasoning spans sit beneath it, with tool-call spans attached to the reasoning step that triggered them. Parentage is the key to reconstructing the sequence. It connects a tool selection to the planning decision that produced it, so malformed arguments do not appear to be isolated tool failures.
Each tool invocation needs its name and version, exact arguments, raw output, latency, and status. Beyond that call record, action-outcome data must show whether a record was written or an API endpoint changed state. Keeping that distinction lets operators see a problem even when the agent sees success. In multi-agent workflows, a shared trace ID must also pass through every hop so that attribution does not stop at a sub-agent boundary.
How the OpenTelemetry GenAI conventions give this taxonomy a vendor-neutral schema
The vendor-neutral GenAI semantic conventions provide a shared instrumentation contract, but not yet a settled one. As of July 17, 2026, no GenAI-specific span, event, metric, or attribute in the dedicated repository is marked Stable. The conventions remain in Development status. Teams should therefore pin convention versions and manage updates as dependency changes, because schema drift can silently break correlation pipelines.
Content capture needs a similarly explicit choice. As of v1.37.0, opt-in fields including gen_ai.system_instructions, gen_ai.input.messages, and gen_ai.output.messages can be recorded as span attributes or in the gen_ai.client.inference.operation.details event. Using the event lets Collectors filter or drop content without changes to the application, which helps meet privacy and compliance needs. The older per-message events were deprecated in that version and should no longer be used. OpenInference extends OTel compatibility with message.tool_calls and tool_call.* fields, while message.tool_call_id links result messages to originating calls.
The GenAI conventions added gen_ai.evaluation.result in v1.38.0 in October 2025. Its evaluation name, score, label, explanation, and response correlation provide a standard connection between an operation and a quality judgment. That connection does not eliminate manual instrumentation. Custom retrieval, evaluation scores, business logic, and multi-model orchestration still need it, while auto-instrumentation offers the fastest start for basic model telemetry. Root spans also need to begin at request entry, because batch exports follow queue size and scheduled delay rather than waiting for the root, and queue overflow can drop it before export.
The three metric layers where span data becomes outcome signal
At the span level, evaluation asks whether each step was good. Relevant scores include tool selection correctness, argument validity, retrieval quality, step-level faithfulness, and reasoning coherence. These judgments locate the first loss of quality. A trace may otherwise show a sequence of successful operations without identifying where the run began to fail.
At the trace level, those steps are assessed against the full objective. Did the agent complete the task, resolve the conversation, follow policy, and maintain context across turns? Individual successes do not settle those questions. Complete trace visibility must include every model call, retrieval, tool invocation, handoff, retry, input, output, latency, cost, and attached version. This is the level where execution becomes a task outcome.
Business-level measurement then links that outcome to the resources used to achieve it. Input and output token counts on each model span let teams work out the cost of each call, while the cost of the agent’s whole run needs the full trace, including tool costs. The number of completed goals is the denominator for cost per completed goal. Cost per successful goal and cost per failed run answer different questions, so raw token totals are insufficient for budgeting. Online evaluation of live traffic and offline evaluation of datasets turn these telemetry layers into quality signals.
Building the correlation layer: joining spans to outcome metrics deliberately
To build the correlation layer, teams must join operation records to evaluation results and trace-level outcomes. The evaluation event provides the attachment point for a score, while trace IDs and parent-child relationships establish where the scored operation belongs. Structured fields supply the dimensions for comparison. These include token usage, tool names, arguments, prompt versions, and model parameters. Prompt and completion content captured in events can also support LLM-as-judge scoring without a separate content logging system.
The practical queries begin with the execution graph. Which reasoning step produced the tool selection that failed? The parent-child relationship connects that decision to the tool invocation. Does higher input token count correlate with worse tool argument validity? That query joins gen_ai.usage.input_tokens on model spans to argument-correctness scores on their child tool-call spans.
Other questions require joining across the metric layers. Which change to a prompt version or model parameter changed task completion rates? The attributes on those model spans must link to the evaluation scores for the whole trace. What is the cost per successfully completed goal versus the cost per failed run? Teams must add up trace costs and group them by completion outcome as well as by whether each call returned without errors.
Failure analysis needs more than those aggregates. Span status and exception events with stack traces help distinguish the step where an error surfaced from the upstream output that caused it. For memory-dependent agents, memory read/write spans and decision branches must also be captured so that context transitions can explain output degradation. Evaluation sampling keeps this process affordable. Scoring a fraction of production traffic provides coverage, while tail-based sampling triggered by errors or high latency captures cases that routine sampling may miss.
What the span-to-outcome correlation reveals in practice: incident investigation as a worked example
Incident investigation makes these connections concrete because the agent’s steps produce the evidence used to judge its result. A trigger span gets the incident context, and a reasoning span comes up with hypotheses. Parallel tool-call spans then query telemetry, look up code ownership, and check dependencies. Another reasoning span synthesizes the evidence before an output span surfaces ranked hypotheses. The trace records how the proposed explanation was assembled.
Parallel checks make this a tree. The correlation layer must preserve concurrent children under the reasoning span that launched them. Meta’s published RCA system illustrates the retrieval challenge by narrowing thousands of candidate changes through heuristic retrieval, code and directory ownership signals, and runtime code graph traversal before an LLM-based ranker scores them. Each retrieval step shapes the evidence that ranking can use. Its quality can therefore be connected to whether the system identified the right change.
The outcome measures include time to hypothesis, hypothesis accuracy, and evidence completeness. Together, they distinguish fast investigation from useful investigation. A poor retrieval can degrade the final ranked output even when the later reasoning is sound, making retrieval quality a predictor of trace-level hypothesis accuracy. Correlation exposes that distinction by joining retriever scores to the final judgment. The resulting failure case points toward what needs evaluation, rather than treating every wrong hypothesis as a model-reasoning problem.
Closing the feedback loop: turning production traces into evaluation cases and then into fixes
That failure case becomes useful operationally when it enters a repeatable improvement process. Aggregate span-level and trace-level monitoring first surfaces failing runs, new failure patterns, prompt-injection attempts, timeout spikes, and quality drift. Risky or failing traces then become evaluation cases for CI, scheduled evaluation, and regression testing. Offline evaluation scores the proposed fixes on task completion, argument correctness, retrieval quality, and context maintenance.
A regression gate then runs those cases against new agent versions, prompt changes, and model updates. The gate tests whether a change closes the failure mode without allowing it to recur unnoticed. Human annotation helps calibrate the automated scores against actual task quality. Because scoring every production trace is prohibitively expensive, a hybrid strategy combines head-based sampling for baseline coverage with tail-based sampling for errors or latency spikes.
The strongest objection remains that correlation looks backward. It explains execution but does not stop a harmful action while it is happening. Runtime gates that block out-of-policy outputs before they leave the inference boundary address that separate need, making enforcement and correlation complementary. Teams still need to manage the schema too, since the telemetry contract can change while it is in Development status.
Persistent runtime state gives the loop continuity across sessions. An infrastructure layer that preserves agent identity, execution history, policy state, and evaluation results lets agents be designed to adapt across runs. That continuity supports improvements beyond a single context window. Agent observability goes beyond agent logging when traces drive measurable changes in behavior.