Agent Memory Models in Production Runtimes
Memory management, not reasoning capability, determines whether production agents actually scale.
The prototype worked fine in the demo. It answered questions, called the right tools, reasoned through multi-step tasks without tripping over itself.
The scale of it appears in the numbers. Most organizations report using AI in at least one function now, but only a small slice of them qualify as genuine high performers, meaning AI actually moves a business outcome rather than sitting in a pilot folder. Gartner's projection is even starker: a large share of enterprise applications are expected to integrate task-specific agents by the end of 2026, up from under 5% the year before, one of the fastest adoption curves enterprise software has seen. Yet McKinsey finds only a minority of organizations are actually scaling an agentic system in production, with a much larger group still stuck experimenting.
Why the gap between "adopted" and "scaled"? It's tempting to blame the models. But the constraining factor isn't intelligence, it's infrastructure. An agent that forgets a user's stated preference, repeats a mistake that was already corrected, or loses the thread on a task that spans multiple sessions is not an agent people keep using. Trust erodes the third time you have to re-explain yourself. And once that trust is gone, no amount of reasoning capability buys it back.
That's the frame for everything that follows: memory, not reasoning, is where production agents actually break. Agents failing to retain and use memory persistently stands as the defining challenge of applied AI in 2026, per the Vektor Memory / Medium research synthesis (April 2026).
What the incumbent framing gets wrong: memory as storage-and-retrieval
Most teams start in the same place. Dump the conversation history into the context window, maybe summarize the older turns once things get long, and call it memory. That's workable for a chatbot answering one-off questions. It falls apart the moment an agent is doing real, multi-step work across sessions.
Nobody had a better answer, so everyone paid the tax.
Part of the problem is a persistent misconception about context windows. A bigger window feels like it should solve memory, doesn't it? It doesn't solve memory. Stuffing a huge block of history into every single API call runs up cost and latency that don't scale, and none of that history persists once the session ends. You're paying more for the illusion of memory, not the thing itself.
Research on this is direct about where agents actually fail. The paper describes agents that "drown in their own accumulating history," paying token costs that climb with every single turn, a management failure rather than a reasoning one. That's not a reasoning failure. That's a management failure.
So here's the diagnostic case. A support bot asks a customer for their account tier again, having already been told twice this week. Neither of these is a model getting dumber. It's a system that never had anywhere durable to put what it learned.
The paper's proposed fix is a reframe: stop treating memory as a storage-and-retrieval problem and start treating it as Agentic Context Management, or ACM, a lifecycle that has to be actively managed, not a bucket you occasionally fetch things from. And the retrieval-only framing actually hides two separate problems by lumping them together. One is personalization, the agent not remembering who it's even talking to. The other is institutional knowledge, the agent not retaining what it learned from being corrected, so the same mistakes get made and the same corrections get issued, and nothing ever compounds. Solve one and you haven't solved the other. That distinction turns out to matter for everything from here on. Three years ago this was accepted as the cost of building with LLMs; the field has since moved, but many production teams haven't.
The four memory tiers and their purposes
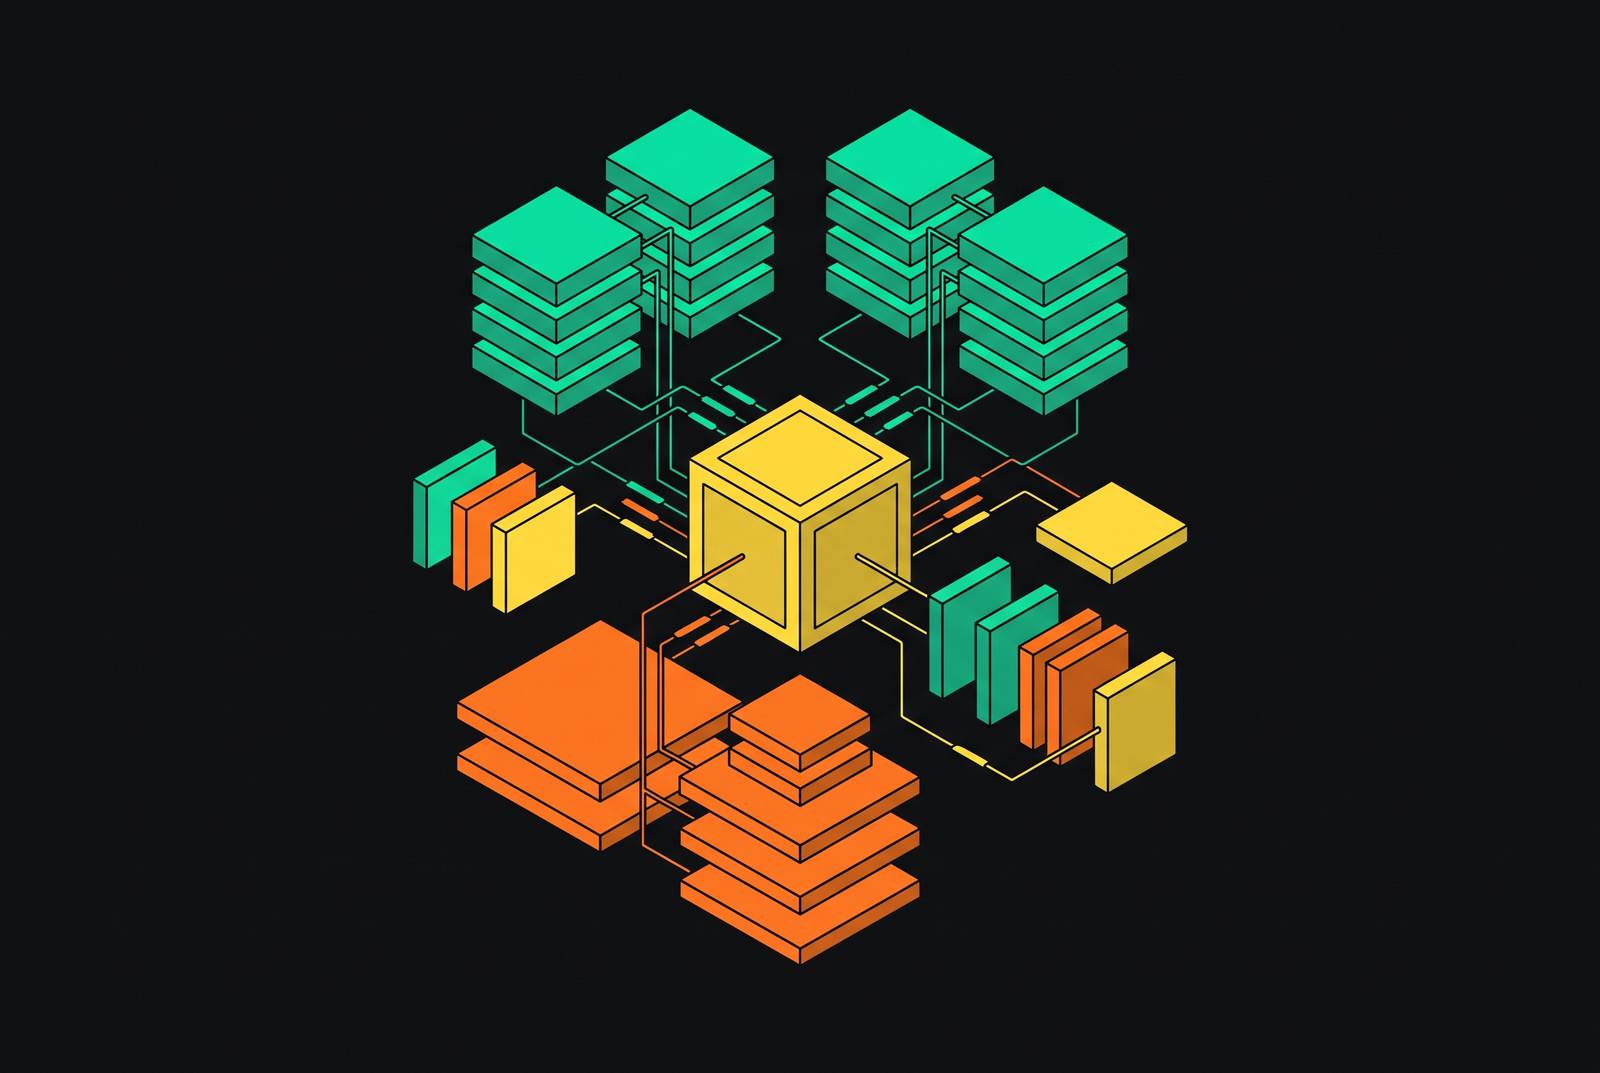
If memory is a lifecycle and not a single store, the next question is obvious: a lifecycle across what, exactly? The field has largely converged, as of mid-2026, on a four-tier model borrowed from cognitive science.
Tier one is in-context, or working, memory. This is everything currently sitting inside the model's context window: the prompt, the conversation so far, tool results, system instructions. It's bounded, it's fast, and it's the most expensive memory there is, priced per token and gone the moment the session resets. It's also, tellingly, the only tier most teams ever build. Without anything beyond it, an agent is a goldfish with excellent vocabulary.
Tier two is external key-value memory, a persistent store, Redis, DynamoDB, Postgres, holding structured facts like user preferences, configuration settings, entity attributes. This is what survives across sessions with reads fast enough not to matter, essentially the agent's preferences file. Without it, a user has to restate their timezone, their name, their plan tier, every single time.
Tier three is episodic memory: an append-only log of every observation, action, and outcome the agent has gone through. This is where time-range queries live, and it's where corrections and learned exceptions actually get stored. Without episodic memory, the procurement agent from the earlier example has no record that the correction ever happened.
Tier four is semantic, or knowledge-graph, memory: structured relational knowledge about entities and how those entities change over time. This tier needs approximate nearest-neighbor search across an embedding space plus multi-hop traversal across relationships. This is the tier that lets an agent understand that the vendor renamed itself, that the new legal entity is the same counterparty, that the org chart shifted last quarter.
Episodic memory wants time-range queries. Semantic memory wants vector similarity. Knowledge-graph memory wants multi-hop traversal. Production systems have to match each tier to the store that's actually built for it, rather than forcing one database to do all three badly.
There's a complementary lens, an OS-inspired model from Letta, formerly MemGPT, that names three tiers after how operating systems manage RAM. Core memory stays inside the context window at all times, like RAM, and the agent itself actively manages it. Recall memory is searchable conversation history, like a disk cache. Archival memory is long-term storage the agent queries only when it needs to. The distinction that matters here is the posture. This is a self-editing model, where the agent decides in real time what to keep close and what to push out to storage, rather than passively waiting on a retrieval system to fetch things for it.
Either lens gets you to the same place: architecture decisions that used to be implicit, buried in whatever database someone had already spun up, become explicit choices once you're mapping tiers to retrieval shapes on purpose.
Memory as a runtime lifecycle: the five primitives of Agentic Context Management
It doesn't tell you how it gets there, when it gets cleaned up, or what happens when a process crashes mid-task.
Architecting comes first: deciding which tier holds which kind of data, and building in redundancy on purpose rather than by accident. Ingesting is next, taking raw interaction, a conversation, a tool call, an error message, and turning it into structured episodic or semantic memory instead of just letting it pile up as text. Scoping decides what's actually relevant to the current turn, and that scoping has to work across an organizational hierarchy, not just for one user in isolation. Anticipating means predicting what the agent is going to need a few steps ahead and pre-fetching it, proactive retrieval instead of reactive lookup. And compacting and consolidation means forgetting what's gone stale while keeping provenance intact, folding sessions together without losing fidelity along the way.
Put those five together and the runtime's actual job comes into focus: orchestrate all five, continuously, for the life of the agent. That's precisely why memory can't be a bolt-on library sitting off to the side. A retrieval library can fetch a vector. It has no view of ingestion, no view of scoping, no view of compaction. It's a tool the lifecycle calls, not the lifecycle itself.
One concrete runtime responsibility makes this tangible: durable resumption. When a process crashes mid-task, the runtime needs to checkpoint agent state so it comes back exactly where it left off, not from scratch, and without losing the episodic record of what already happened. LangGraph's directed cyclic graph model is one production example of checkpoint-based state persistence built for exactly this.
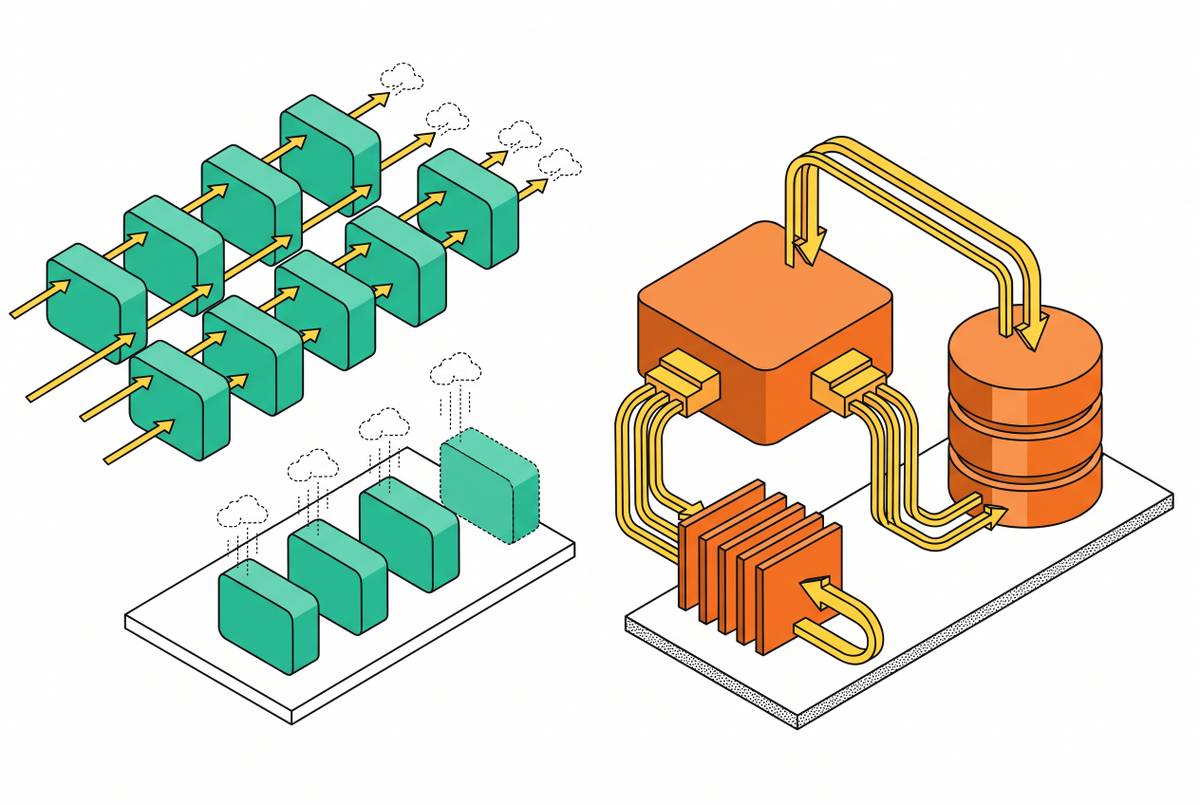
Cost control is the other place the lifecycle is visible concretely, through hot, warm, and cold tiering. Separating short-term, thread-scoped state from long-term, cross-thread stores is now standard practice, not some advanced optimization reserved for teams at scale. Redis's own dual-tier approach pairs short-term in-memory storage for working state with a durable long-term store that supports semantic search. The two-tier split is where most serious builds start, full stop.
There's a failure mode here that's easy to miss until it bites. In stateful deployments, a Slack bot, a Teams integration, agent state needs a real store adapter implementing the StateStore contract. Skip that, and the SDK silently falls back to an in-memory store, which means state vanishes the moment the process restarts. Persistence, in that setup, is an illusion. It looks like it's working right up until a deploy or a crash proves it wasn't.
The open frontier is organizational context. Almost everything ACM does today operates over a single user. Scoping across an org chart is a different problem than scoping across one person's conversation history, and the tooling for it is still young.
How benchmarks reveal what memory architectures do under load
Before any of this could be measured properly, memory quality claims were mostly vendors describing their own systems in their own words. That changed in 2026, arguably the most significant shift in the whole category: standardized benchmarks now let genuinely different architectures get compared on the same evaluation set.
Three benchmarks define that landscape now. LoCoMo runs 1,540 questions across single-hop, multi-hop, open-domain, and temporal recall, and it's the first benchmark that pulled memory quality out of the realm of self-reported marketing claims. LongMemEval runs 500 questions across six categories, single-session-user, single-session-assistant, single-session-preference, multi-session, temporal-reasoning, and knowledge-update, and it leans hard on that last one, knowledge updates, which is exactly the institutional-knowledge challenge from earlier in this piece. BEAM operates at a much larger token scale, large enough that you genuinely cannot cheat it by just expanding the context window, which makes it the benchmark most relevant to production-scale deployments.
Measuring correctness (via LLM-judge), BLEU and F1 (LoCoMo only), token consumption, and latency together stops teams from optimizing one axis at the expense of others.
The payoff figure comes from Mem0's algorithm, which uses single-pass hierarchical extraction paired with multi-signal retrieval: 92.5 on LoCoMo, 94.4 on LongMemEval, at a query footprint that stays token-efficient. The two biggest jumps over the prior version of the algorithm came on temporal reasoning and multi-hop reasoning: those are the two categories that most directly reflect what actually happens with a real user's history, facts pile up, facts change, and the agent has to track both.
But the story isn't a clean sweep. On BEAM, at the largest token scale tested, scores drop meaningfully compared to moderate scale. That drop is the honest part of this section. It shows that temporal abstraction at real scale, and identity that holds together across many sessions, are still open problems, not things current architectures have quietly solved. That's the frontier the category is visibly working toward, not something already checked off. What the benchmarks don't yet capture, per arXiv:2607.21503, is latency, token efficiency, and context-rot resistance, the open frontier the category is moving toward.
Eight frameworks and what each optimizes for
With tiers and lifecycle and benchmarks in hand, the practical question becomes which framework to actually build on. The field splits cleanly into two camps here: frameworks built around conversation context, meaning personalization, and frameworks built around accumulated operational knowledge, meaning institutional memory. Which one an agent needs depends entirely on which problem it actually has.
Before any of that, there's a gate to apply honestly. If an agent is stateless, handles one session at a time, or processes each request independently with nothing carrying over, it doesn't need a memory framework at all. Bolting one on anyway just adds complexity with nothing to show for it.
Mem0 covers personalization plus some institutional memory, using a vector-and-graph hybrid architecture. It's Apache 2.0 licensed with a large, active community as of 2026, offers both a managed cloud option and self-hosting with no lock-in, and is probably the most accessible entry point going: the managed API handles extraction, deduplication, and conflict resolution on its own, and it already integrates with 21 frameworks and 20 vector stores. It's also the current benchmark leader, 92.5 on LoCoMo and 94.4 on LongMemEval, at roughly 6,956 and 6,787 tokens per query respectively, with its strongest gains occurring on temporal and multi-hop reasoning. The trade-off is right there in the memory-class label: it's personalization-first, and institutional knowledge takes extra configuration to get working well.
Hindsight covers both personalization and institutional memory, but it was built from the ground up with institutional knowledge as the priority, using a multi-strategy retrieval architecture. It's MIT licensed with a growing GitHub presence, in the low thousands of stars by most accounts, and offers both managed cloud and self-hosting with no lock-in. The honest trade-off: its ecosystem is smaller than Mem0's or Letta's right now, so expect less community tooling and fewer integrations out of the box.
Letta, formerly MemGPT, covers both personalization and institutional memory using the tiered, OS-inspired architecture already covered above, core, recall, archival, backed by either Postgres or SQLite depending on setup. It's Apache 2.0 licensed with a substantial following on GitHub, available both as managed cloud and self-hosted with no lock-in. Its strength is real statefulness: agents persist across restarts and actively call tools to pull from archival memory rather than waiting to be handed context, and it plays well with local models like vLLM and Ollama. That self-editing posture is genuinely distinct among the options here, and it's worth the setup cost for teams that want an agent managing its own memory rather than a system managing it on the agent's behalf.
Choosing between these, or any others in the category, ultimately comes back to the diagnostic question this piece opened with: is the challenge personalization, institutional memory, or both, and does the agent's statefulness require any of this? Get that answer right, and the rest of the architecture follows from it.
Sources
- State of AI Agent Memory 2026: Benchmarks & Trends ...
- The State of AI Agent Memory in 2026: What the Research Actually Shows | by Vektor Memory | Medium
- Agentic Context Management: Solving Agent Memory and Cost by Treating Them as Lifecycle and Architecture Problems
- MEMTIER: Tiered Memory Architecture and Retrieval Bottleneck Analysis for Long-Running Autonomous AI Agents