Where Agent-Driven Automation Is Actually Cutting Business Costs in Deployed Systems Today
Agents pay off where tasks repeat, follow rules, and cost people most.
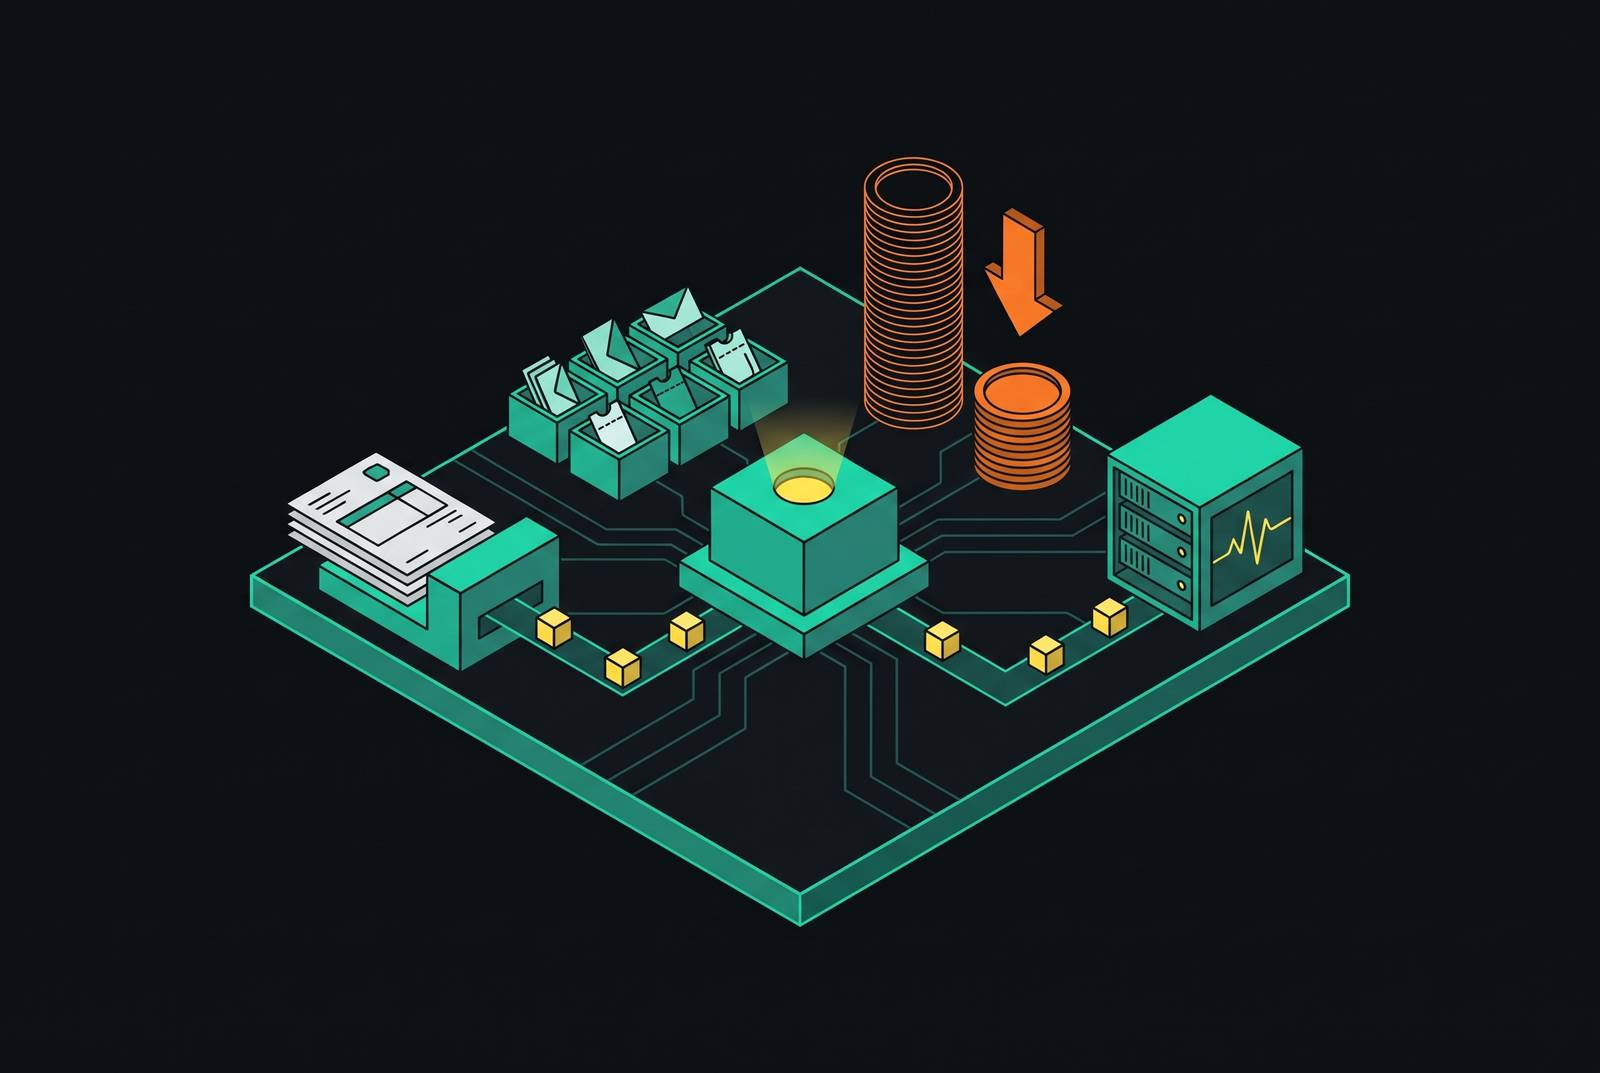
Agent-driven business AI cuts costs when it completes a task for less than human execution costs, after compute, maintenance, and human review are included. Customer service, finance, routine software development, and HR each have strong reasons to use agents. The best deployment choice depends on task volume, data structure, and human cost per task.
Why per-task unit economics explain agent ROI better than aggregate savings claims
The aggregate savings claims circulating in 2026 make automation sound like a company-wide result. A headline ROI percentage can combine a contact center with a finance team, even though their labor costs, workloads, and error tolerances differ sharply. That hides the decision a business actually faces. Which work should move to agents first, and what will it cost to complete that work successfully?
Per-task unit economics makes the comparison more useful. It compares agent-handled and human-handled cost for the same work, then considers how often that work occurs. Ticket resolution, invoice processing, and appointment booking are promising because they repeat and follow reasonably clear rules. Bespoke work follows a different economic pattern. A low-volume task that demands judgment and frequent exception handling can be technically possible to automate without being a good first investment.
The distinction also helps explain deployment priorities. When a task comes up often, a large saving each time can pay back the cost of building and running an agent sooner than a similar saving on work that rarely comes up. But frequency alone is not enough. If an agent needs a lot of human review, the labor it seems to save can be used up before the task is done.
What structural features make a business function a good candidate for agent cost reduction
A useful diagnostic is the volume–structure–human-cost filter. The first two conditions, high task volume and well-structured data, predict where agent economics are most favorable. A support team handling thousands of tickets a day can spread agent infrastructure expense very thinly, while a legal team handling a handful of bespoke contracts cannot.
Structure determines how much supervision that work needs. Invoices with standard fields, support tickets with predictable intent categories, and appointment requests with clear slots give agents defined inputs to work from. Fewer ambiguities mean fewer errors and less review. With unstructured inputs, the work can shift to people who must check and fix the agent’s output.
High human labor cost amplifies these advantages. Senior engineer time and specialist analyst time can make partial automation worthwhile even at moderate volume. Code review’s human cost per task can support substantial savings even though its volume may be lower than customer support. Work with low volume, unstructured inputs, and cheap human execution is a weaker place to start, even if the automation looks impressive.
Customer service and support: where agent cost ratios are the most documented and the payback is fastest
Customer service has the clearest documented case because the work comes up often and is fairly predictable. Agents can handle Tier-1 and Tier-2 queries, including ticket triage, FAQ resolution, order status, and appointment scheduling. These tasks recur throughout the working day. At enterprise volume, a lower cost per resolved interaction accumulates into substantial savings quickly.
Antino’s analysis frames the difference as roughly a 9x cost reduction per resolved interaction. The analysis also emphasizes the distinction between deploying agents and optimizing their costs. Its central qualification is therefore economic as well as technical, because an agent’s presence does not by itself establish that its operation is efficient.
Much of it involves categorizing a request, responding from a knowledge base, or dealing with a defined order or appointment. When escalation is necessary, context transfer supports the handoff. The useful boundary is between work the agent can resolve and work that needs a person, rather than between an entirely automated service operation and an entirely human one.
For a business with high-volume support, the deployment lesson is to start here. Finance offers a different route to favorable economics. Its volume is lower, but the human cost of each task is higher.
Finance and accounting automation: lower volume, higher per-task human cost, equally strong ratios
Finance and accounting have structured information that is costly for people to process. Invoice handling, reconciliation, and financial close have defined inputs, yet people can be slow or make mistakes as they do this repeated work. This gives agents a favorable starting point. Agents can cut costs by doing more of the work on standard cases while leaving some financial decisions to people.
But what about exceptions, regulatory judgment, and audit requirements? Those are genuine limits on autonomous execution. The per-task argument applies to the structured majority of work, while exceptions go to people. That division can still reduce cost compared with having a person handle every invoice from beginning to end. The cost of exception handling is part of what it costs to run agents, and can coexist with savings.
The reported compression of financial close from roughly ten days to roughly three shows that such overhead need not erase the benefit across the function. Elapsed time provides evidence that retaining human involvement can coexist with a substantially shorter process, though it does not itself measure a per-task cost ratio. The relevant comparison remains the cost of completing the work, including the exceptions.
Expensive human processing can sustain favorable economics when the inputs are clear enough to constrain the agent’s work. Software development takes that logic further into knowledge work. Senior engineering time is costly, but the task mix requires a more careful distinction between routine production and judgment.
Software development and agentic coding: high per-task human cost drives ROI even at lower volume
Software development can justify agents without matching the volume of a contact center. Senior engineering time is among the most expensive task-level human costs, so partial automation can produce large absolute savings. Yet not all coding work fits equally well. Routine pull request review, boilerplate generation, test writing, and documentation are stronger candidates than work dominated by architectural judgment.
These routine tasks also occupy substantial junior engineering time. Automating them can reduce repetitive effort while freeing senior engineers for architecture and judgment-heavy work. The benefit extends beyond a faster individual task. It changes where costly human attention is spent, although that productivity gain should remain distinct from a direct reduction in expenditure.
McKinsey’s State of AI 2026 report says a meaningful share of large businesses use agentic coding to build custom internal applications as replacements for external SaaS or vendor solutions. This introduces a second source of savings. Avoided ongoing licensing fees can compound over time, rather than appearing only as a one-time development saving. That is a different economic claim from producing code more cheaply, even when both arise from the same deployment.
For teams building these agents, scope is a practical cost control. Giving an agent too many tools at once reduces tool-selection accuracy, while a routing layer can narrow the visible tools to a small subset per call. HR gets less attention than coding, but its repeated work and the high cost of coordinating it also make it a good place to start with agents.
HR screening and onboarding: underappreciated volume and compounding time savings
HR screening and onboarding fit the same economic filter. Recruiter and coordinator time is expensive, growing businesses can generate significant volume, and initial screening steps have enough structure for autonomous handling. The work is easy to underestimate. Its cost is distributed across repeated administrative steps rather than concentrated in a single conspicuous task.
IBM’s documented reduction in HR administrative costs supports the case for this function. HR shares finance’s combination of administrative overhead and structured processes. The evidence here is less detailed than the support comparison, however. It supports treating HR as a candidate without establishing a universal per-task ratio.
Client onboarding in professional services follows a related pattern. Agents handle intake processing, project channel creation, template population, and delivery team briefing, reducing workflows that previously required multiple hours of coordination to a fraction of that time. The savings accumulate across connected steps. But those gains remain gross savings until the expense of running and supervising the agents is included, which brings the analysis to the other side of the ledger.
Why managing AI compute cost is the variable that determines whether the per-task ratios hold
AI operating cost determines how much of the labor saving remains. An agent can be cheaper than human execution in isolation while delivering much less net benefit once compute, maintenance, and review are counted. Astar Labs Hub makes this distinction explicit. Its analysis says total cost of ownership can eat up a large share of gross savings when businesses overlook those expenses.
This is a reason to manage agent operating cost as carefully as the labor cost being replaced. The same per-task framework works on both sides of the comparison. Human execution has a cost, but so does reaching a successful result through an agent, including any retries and human intervention.
Model routing offers a concrete way to control that expense. A dispatcher-first architecture sends simple tasks to inexpensive models and reserves frontier model compute for complex reasoning. Astar identifies this as the most underused cost lever in AI operations. The economic purpose is to match the cost of inference to the demands of the task, rather than paying for the most capable model on every call.
Cost per token can make a cheaper model look attractive even when repeated attempts make it more expensive than a mid-tier model that succeeds first time. Cost per successful task completion captures that difference. For teams evaluating deployments, this is the useful measure because it includes the effort required to finish.
What the infrastructure layer beneath agents has to do with whether the per-task economics survive production
Successful completion also depends on the operating environment beneath the model. Agents need agent identity, persistent memory, execution lifecycle, and governance to work reliably beyond isolated sessions. These are not separate from the economics. Agents that repeatedly lose context or cannot act on a schedule do not operate under the conditions assumed by the favorable deployment cases.
The “goldfish problem” makes the connection especially clear. An agent that resets at every session creates more human review overhead because it cannot retain context across interactions. Tiered memory addresses this through active working memory, indexed recall for recent sessions, and cold-storage archival for historical interactions. An agent handling a customer’s fifth ticket need not start without the context of the previous four. In multi-agent workflows, shared memory also reduces coordination overhead by making context readable and writable across agents.
Scale introduces another source of expense, which is agent sprawl. Deploying many agents without unified management creates operational disorder that can erode task-level savings. Another monitoring dashboard does not resolve that problem. A management plane must handle orchestration, governance, and adaptability, while the supervisor-and-worker design in the 2026 reference architecture organizes requests into plans and dispatches work to narrowly scoped agents. This applies the coding section’s scope discipline across the system.
A dedicated agent operating system layer brings identity, execution, policy, memory, and lifecycle into a full control plane. Purpose-built operating environments aim to manage persistent state and execution policy without accumulating the overhead that weakens per-task ratios. Customer service, finance, software development, and HR need agents that retain context, act on schedules, and work within governance, so infrastructure belongs in the cost comparison before a promising pilot becomes a production commitment.